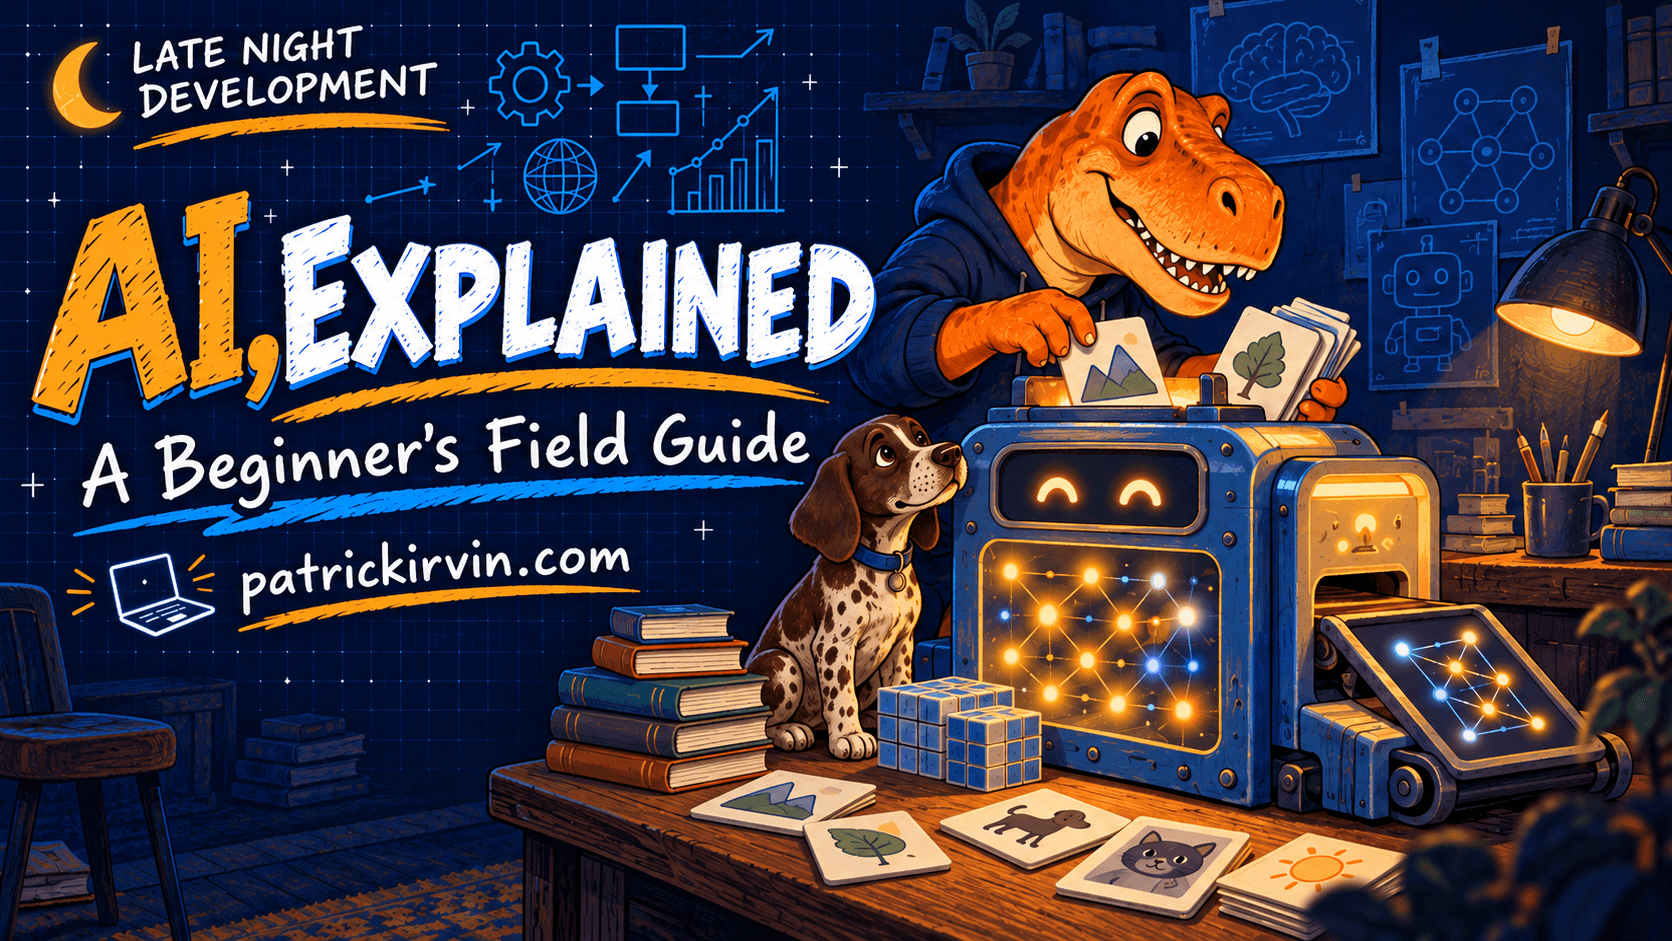
The second article in this series separated training from inference: training builds the model, once; inference is the model responding, every time. That distinction is useful, but it skips past the more interesting question. What does training actually do?
Understanding that—without slipping into treating a model like a person—is the point of this article.
The basic flow
Training follows the same basic shape across almost every modern model:
- Examples enter training. Enormous amounts of text, images, or audio—far more than any person could read or view in a lifetime.
- Weights adjust toward patterns. The model's internal parameters shift, incrementally, toward whatever statistical regularities keep showing up in the examples: which words tend to follow which other words, what a cat tends to look like, how a sentence in English tends to map to one in French.
- The model generalizes. After enough examples, the model is not just memorizing specific sentences or images—it is capturing patterns general enough to apply to inputs it has never seen before.
- An answer is generated later. All of that happens before you ever type a prompt. What you experience as "the model answering" is step four—inference—drawing on patterns that were locked in during steps one through three.
That is the entire mechanism. No understanding is required for it to work, which is exactly the part that trips people up.
Use this when someone says the AI "knows" something
"The AI knows that" is a sentence worth pausing on. A model does not know things the way a reference book or a database does—it has not stored an address and retrieved it; it has generalized a pattern well enough to reproduce something close to correct text about it.
This distinction earns its keep in three specific situations:
- Someone claims the AI "just knows" a fact. What it actually has is a learned pattern that correlates with the fact—usually accurate, sometimes not, with no internal flag telling it which case you are in.
- You are comparing training data between tools. A model trained mostly on code behaves differently than one trained mostly on prose, because the patterns available to learn from were different, not because one tool is smarter.
- You need to explain a model's limits to someone else. "It wasn't trained on that" is a more accurate—and more useful—explanation than "it doesn't know," because it points at the actual cause.
Reality check: three things training is not
Patterns are not experience. A model trained on millions of descriptions of heartbreak has not felt one. It has learned what language about heartbreak statistically looks like, which is a genuinely different thing from having lived through it—even when the output reads as if it understands.
Training is not a live database. A model's knowledge has a cutoff, fixed at whenever its training data was collected. Nothing you tell it in a conversation updates that underlying training—the model is not quietly learning from you mid-chat. If a model needs current information, something else has to supply it in the prompt (a search result, a document, a fetched page)—training alone cannot.
Relevance matters more than volume. A model trained on a mountain of loosely related data is not automatically better than one trained on a smaller, more targeted set. This is exactly why a general-purpose model can sound fluent and still be noticeably weaker on your specific domain than a model—or a RAG setup, from the last article—tuned closer to it.
Why this matters more than it sounds like it should
None of this is abstract trivia. It is the direct explanation for two things every AI user eventually runs into.
First, it explains confident wrongness. A model asked about something adjacent to, but outside, its training patterns will often still generate fluent, well-formatted text—because fluency is what the training process optimized for, not a built-in flag for "I'm not sure." The next article in this series spends real time on exactly this failure mode.
Second, it explains why two different tools can give you meaningfully different answers to the same question. They were not shown the same examples, so they generalized different patterns. "Which AI is right?" is often the wrong question; "which AI was trained on material closer to what I'm asking about?" is usually the more useful one.
In plain English
Training shows a model enormous amounts of data and adjusts it until it reliably generalizes patterns from that data. That process happens once, in advance. Every response you get afterward is the already-trained model applying those patterns to your specific prompt—not the model learning in real time, not the model consulting a live database, and not the model drawing on anything resembling personal experience.
Try this tonight
Pick something you are confident an AI tool "knows" well—a programming language, a historical period, a well-documented process. Then pick something adjacent but less common: an obscure library, a niche historical event, an internal process at your company. Ask about both. Notice the difference in specificity and hedging. That gap is the training data talking, not a difference in how hard the model is trying.
Next in the series: How Chatbots Make Answers. We will walk through what actually happens between your prompt and the model's response—and why "fluent" and "verified" are not the same thing.